Why Static Knowledge Bases Like Confluence Are Failing Your Team (And What to Use Instead)
Static wikis weren't built for the speed of modern engineering. Here's why they break, and what an AI-native knowledge base looks like.
Every company has one.
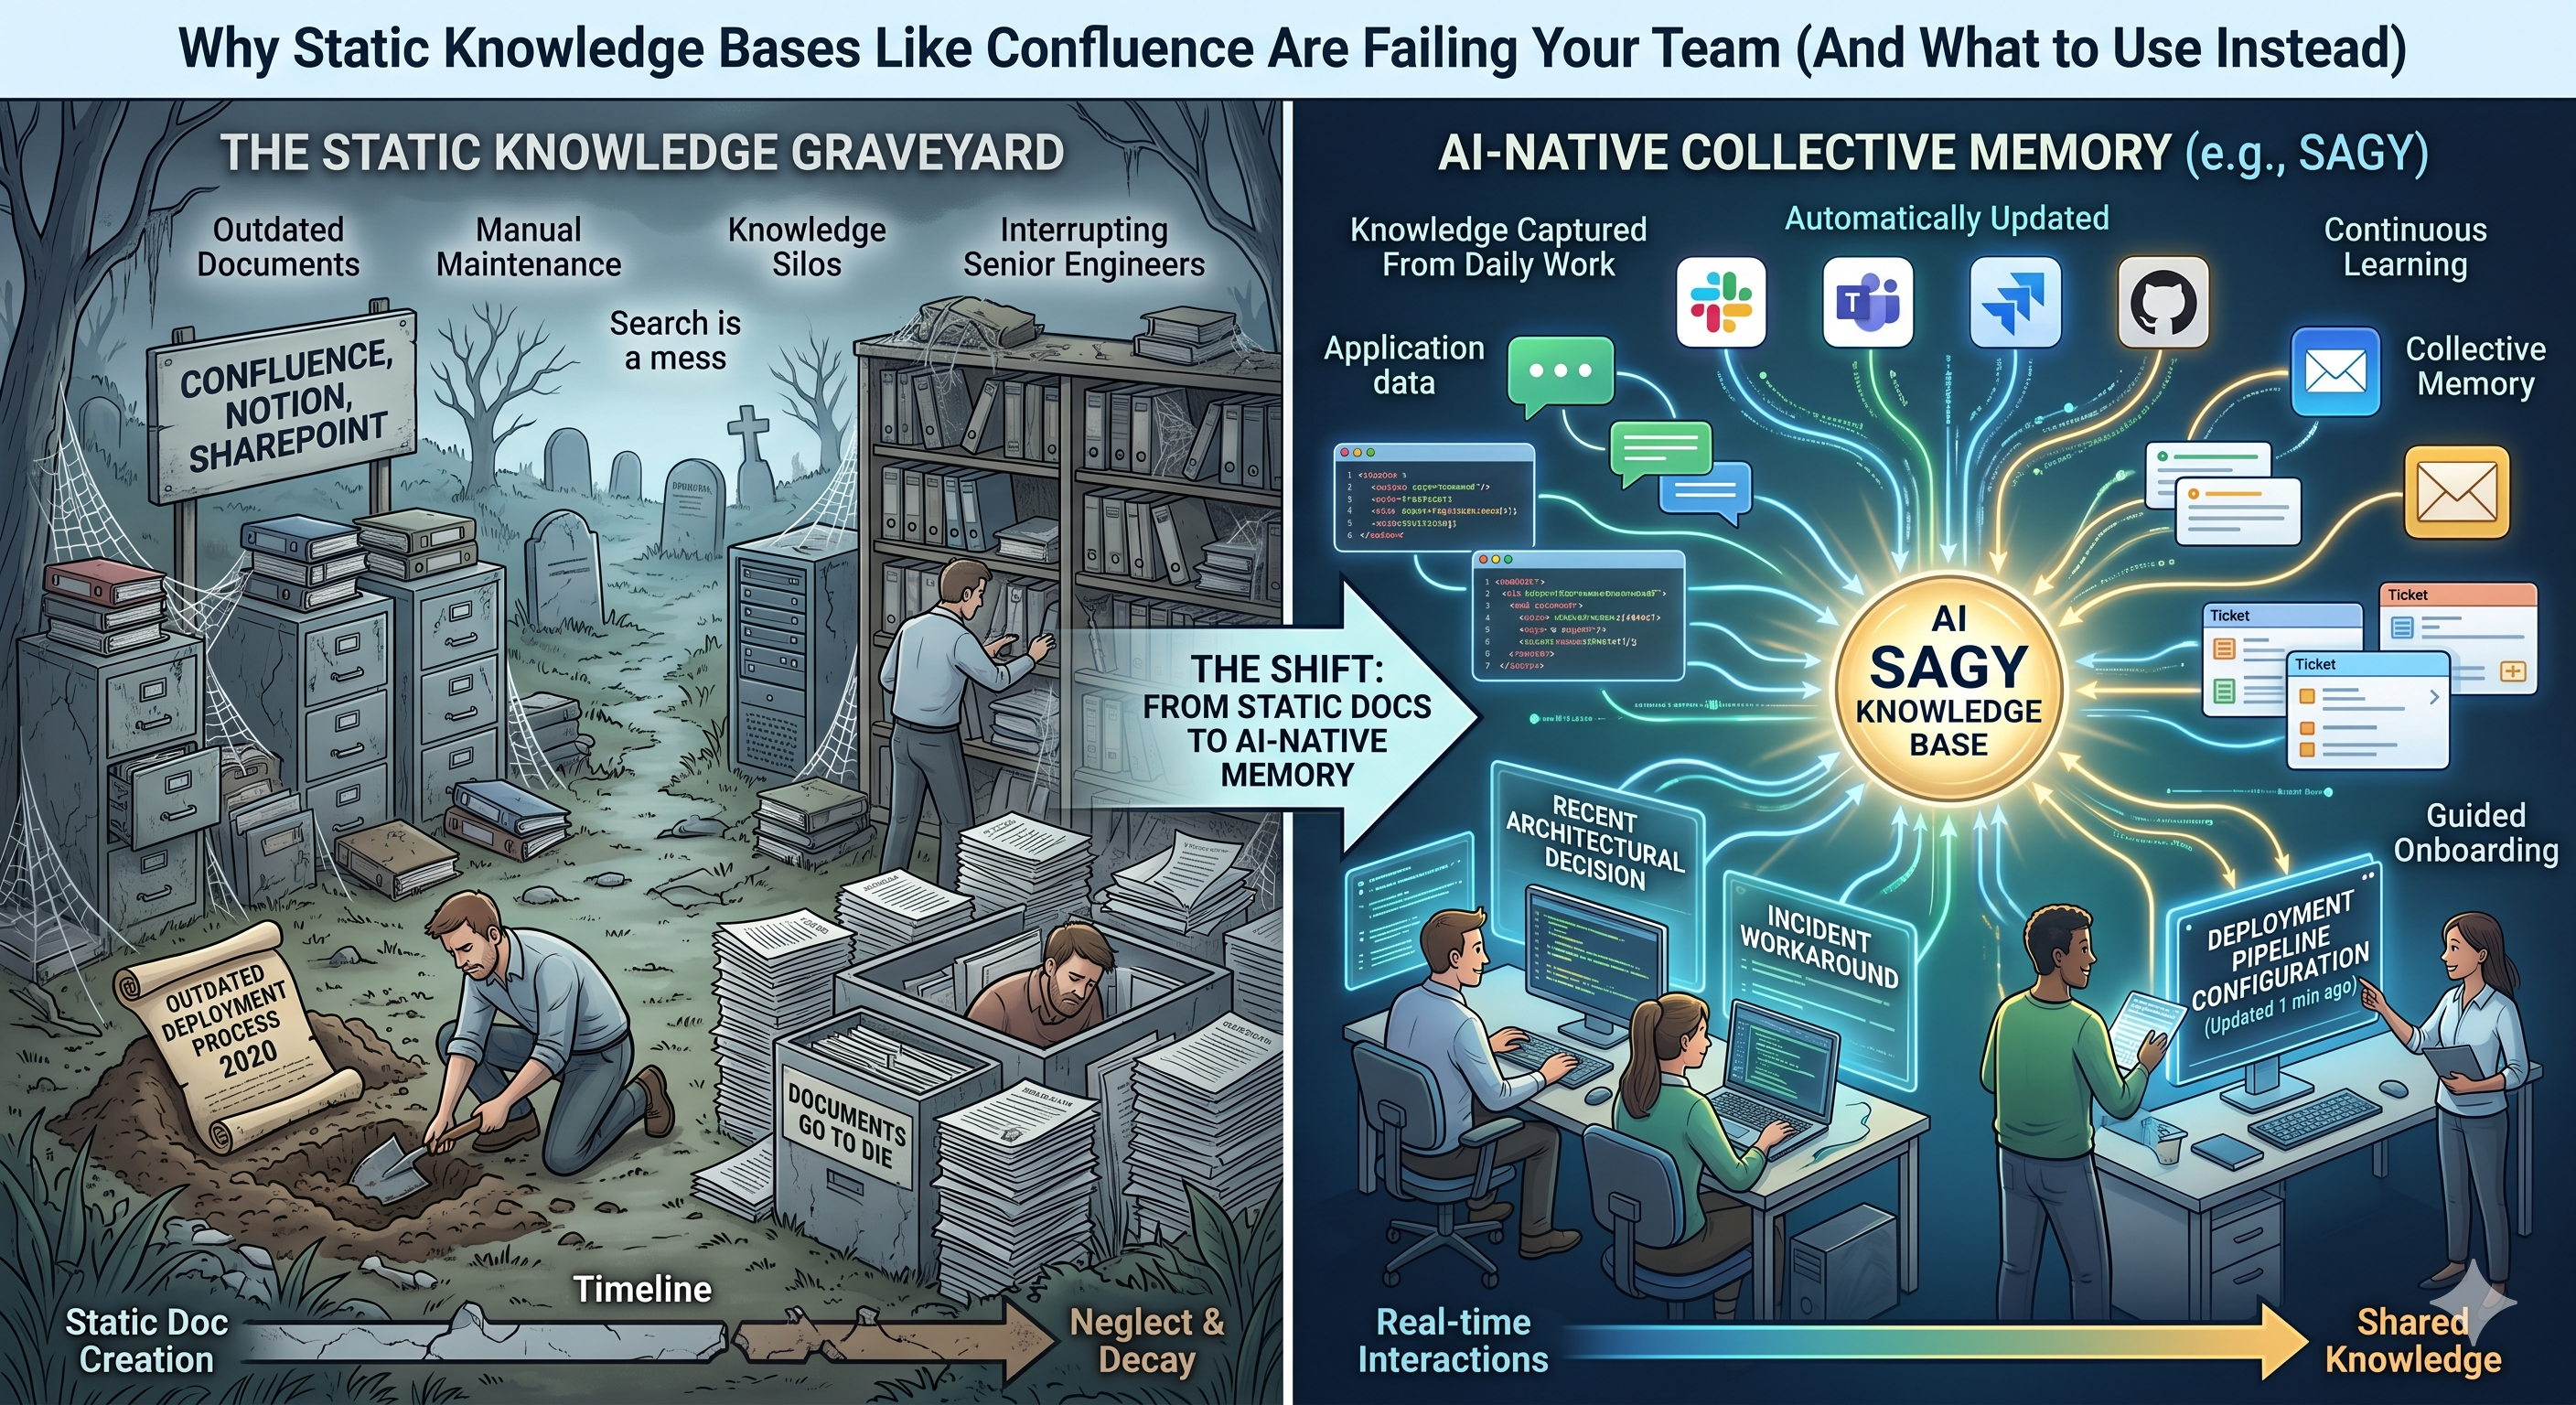
A Confluence space full of pages nobody reads.
A Notion wiki that was last updated eight months ago.
A SharePoint graveyard where documents go to be forgotten.
We've all agreed, silently, collectively, to pretend these tools are working.
They're not.
Static knowledge bases have become one of the biggest silent productivity drains in modern engineering teams, and most leaders don't even realize the scale of the damage.
The Problem With Traditional Knowledge Management Software
Static knowledge bases were built on a compelling promise: write things down once, and everyone will always know where to find them.
That promise worked, until software started changing faster than documentation could keep up.
Here's what actually happens.
Someone documents a process.
Three months later, the process changes.
The doc doesn't.
Six months after that, a new engineer follows the outdated doc, breaks something, and spends two days debugging a problem that shouldn't have existed.
Meanwhile, the senior engineer who knows the real answer?
Still answering the same DM they've been answering every quarter for two years.
The knowledge exists.
It's just locked in someone's head, buried in a Slack thread from 2022, or sitting in a Jira comment nobody thought to archive.
This isn't a discipline problem.
It's a design problem.
Traditional knowledge management software treats knowledge as a document management task, and then wonders why nobody keeps the documents up to date.
Why Search-Based Knowledge Retrieval Doesn't Solve the Problem
The standard response to "our wiki is a mess" is simple:
"Just use search."
But keyword search is the wrong solution to the wrong problem.
When debugging a production issue, engineers rarely search for documents, they search for context:
- Why this decision was made
- What workaround exists
- Who last touched the system
- What broke the last time this happened
Search assumes:
- You know what you're looking for
- The information exists
- The document is labeled correctly
- The information is still accurate
In fast-moving engineering teams, none of those assumptions reliably hold.
And even when search works, when you type the right query and get a plausible result, you still have to read through multiple documents, cross-reference tickets, and hope the information isn't outdated.
That's not knowledge retrieval.
That's archaeology.
Why Knowledge Bases Don't Scale
Static knowledge bases don't scale with your company.
They slow down with it.
- The more people you hire, the more they contribute.
- The more they contribute, the messier the structure becomes.
- The messier the structure becomes, the harder it is to find anything.
- The harder it is to find anything, the less people update it.
Round and round, until you have a thousand pages of documentation that nobody trusts.
Onboarding a new engineer?
Budget weeks, sometimes months, while they slowly reconstruct the history of the system from scattered notes and conversations.
Knowledge handoff when someone leaves?
Schedule an exit interview and hope they remember everything important.
This is the real cost of poor knowledge management.
Not the subscription fee, the hidden productivity tax paid by every engineer who spends time searching instead of building.
The Hidden Cost of Engineering Interruptions
For engineering teams, the biggest cost of poor knowledge management isn't documentation.
It's interruptions.
A senior engineer is deep into debugging a production issue.
A new developer joins the team and asks a familiar question:
- "Why does this service restart when memory spikes?"
- "What's the workaround for the API timeout issue?"
- "Who approved this architecture change?"
The answer exists.
Somewhere.
Maybe in a Slack thread from last year.
Maybe in a Jira ticket comment.
Maybe only in someone's memory.
So the senior engineer stops what they're doing, and answers.
Again.
This repeats dozens of times per month. Not because engineers are careless, but because knowledge lives in conversations, not documents.
Over time, these interruptions quietly drain productivity.
Not dramatically.
But constantly.
And that slow drain is exactly what makes traditional knowledge bases fail engineering teams at scale.
What an AI-Native Knowledge Base Actually Looks Like
The shift happening right now isn't just about making search smarter.
It's about rethinking what knowledge management software is supposed to do from the ground up.
Knowledge shouldn't require a context switch.
If your team lives in Slack, Microsoft Teams, Jira, and GitHub, that's where knowledge should be captured and surfaced. Not in a separate tool that requires someone to stop working and manually document something.
Knowledge should update itself.
- When a process changes, the system should detect it.
- When someone asks a question that reveals missing context, the answer should be captured.
- When an engineer explains something important in a thread, that explanation should become reusable knowledge.
Not disappear when the conversation ends.
Static Knowledge Base vs AI-Native Knowledge Base
This isn't just a technical shift.
It's a behavioral one.
Real Example: What Happens Without Automatic Knowledge Capture
In one engineering team we worked with, onboarding new developers followed a familiar pattern.
New hires spent their first weeks asking questions like:
- "Where is the deployment pipeline configured?"
- "Why does this component behave differently in staging?"
- "What's the correct rollback process?"
The answers existed, but they were scattered across Slack threads, Jira comments, and tribal knowledge held by senior engineers.
Senior engineers reported spending multiple hours per week answering repeated questions, many of which had already been answered before.
Once automatic knowledge capture was introduced, those repeated answers began turning into reusable knowledge, searchable and accessible to everyone.
The biggest change wasn't technical.
It was behavioral.
Engineers stopped repeating answers, and started building collective memory.
Sagy: An AI-Native Knowledge Base Built for Modern Engineering Teams
Sagy is a knowledge base, but an AI-native one, built from the ground up for the way engineering teams actually work.
Not the way documentation tools worked in 2010.
Instead of relying on manual updates, Sagy connects to the tools engineers already use, Slack, Microsoft Teams, Jira, GitHub, and documentation systems.
It automatically detects when something important happens:
- → An architectural decision in a Slack thread
- → A workaround discussed during an incident
- → A key explanation added to a Jira ticket
- → A post-mortem insight shared after an outage
Those moments become reusable knowledge.
Not lost conversations.
Not forgotten context.
Just knowledge, available when the next engineer needs it.
And when someone asks a question later, the answer isn't recreated.
It's retrieved.
Why This Problem Matters More Than Ever
Ten years ago, documentation worked differently.
Teams were smaller. Systems were simpler. Changes happened more slowly.
Today, engineering environments are dramatically more complex:
- Distributed teams collaborate across multiple tools
- Systems evolve weekly, sometimes daily
- Architecture decisions accumulate faster than they can be documented
- Knowledge lives inside conversations, not just files
At the same time, AI has changed what's technically possible.
Modern systems can now understand conversations, extract decisions, and surface context in ways that weren't possible just a few years ago.
That combination, growing complexity and improving AI, is why traditional knowledge bases are struggling today, and why AI-native systems are emerging as the next generation of knowledge infrastructure.
Static Knowledge Bases Had Their Time
Confluence, Notion, SharePoint, and similar tools were the right solution for a different era, when documentation moved slower than the systems it described.
That era is over.
Modern engineering teams move too fast. Systems change too frequently. Context spreads too widely.
The companies that win the next decade won't be the ones with the most documentation.
They'll be the ones with the best memory.
Stop Letting Knowledge Slip Through the Cracks
Most teams don't lack documentation.
They lack usable memory.
If your engineers are:
- Answering the same questions repeatedly
- Digging through outdated pages
- Rebuilding context from scratch
- Relying on tribal knowledge
Then the problem isn't documentation.
It's memory.
And memory should be automatic.
Want to see what your team already knows, but can't easily access?
Run a short pilot inside your engineering workflow.
You might be surprised how much knowledge your team is already creating, and how much time is being lost because it's not captured.
👉 Learn more about how Sagy builds your team's memory automatically.